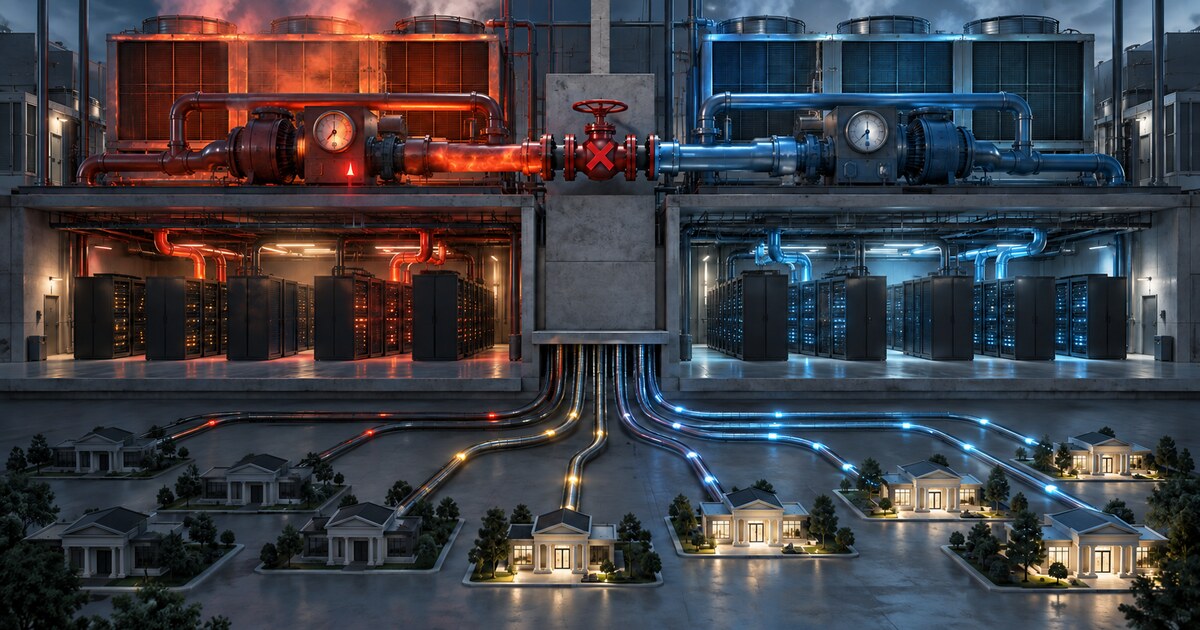
A multi-day Sharetec outage tied to a data-center cooling failure disrupted core processing, online and mobile banking, debit transactions and other member services at credit unions across the eastern United States. The incident is a direct test of whether hosted-core redundancy survives a shared physical failure—and whether credit unions can sustain member service while a provider restores institutions in sequence.
The disruption began around noon Tuesday, September 15, according to affected credit unions cited by the Butler Eagle. First Choice Federal Credit Union said hundreds of credit unions east of the Mississippi went offline after a hardware failure at a provider data center. By Friday, technical teams had worked for more than 56 hours and approximately 100 credit unions had been brought back online, but restoration was incomplete.
CUToday.info reported September 20 that at least one affected institution closed Friday, while another had restored most services but still lacked online and mobile banking. Sterling United Federal Credit Union's CEO told the publication that overheating and a cooling failure triggered the disruption and that failover did not work properly. Sharetec also postponed its September 20–23 users conference, saying its customers were the priority.
Affected credit unions described the event as a service-availability problem, not a cyberattack or data breach. Methuen Federal Credit Union's notice, for example, said no unauthorized access to member data had been identified. CUToday.info reported that Mills42 Federal Credit Union said Sharetec had confirmed no transactional data was lost. Those statements are important, but they do not remove each institution's obligation to reconcile its own records and confirm completeness after recovery.
Redundancy has to cross the failure domain
A secondary server, network path or recovery environment is not independent if it depends on the same cooling plant, power path, control plane, staff access or restoration process. Vendor due diligence should map those shared dependencies explicitly—not settle for a statement that systems are redundant.
Technology and business-continuity leaders can ask for the provider's architecture at the level that matters operationally: which facilities host production and recovery workloads; whether cooling, power, network, identity and backups share upstream components; what event triggers failover; who has authority to invoke it; and when that path was last exercised under load. The evidence should include actual recovery results, not only design documents or certification reports.
The same review should extend to digital banking, cards, bill pay, call-center tools, document systems and general-ledger interfaces. A core outage can leave some channels working while their balances, limits or transaction histories are stale. That is a more complicated operating state than a clean all-or-nothing failure.
Recovery order is a member-service control
When many institutions share a provider, recovery capacity becomes a queue. Credit unions should know how the vendor prioritizes clients, which service comes back first within an institution and what dependencies must be reconciled before another channel is opened. A nominal recovery-time objective is incomplete without the tested sequence behind it.
A practical exercise should time five stages separately: provider restoration, credit-union validation, transaction reconciliation, member-channel reopening and backlog clearance. Leaders should define who can accept degraded service, who can close or reopen a branch, which card or cash alternatives can be offered and when fee waivers or provisional accommodations apply.
Member communications belong in the same runbook. Status pages, phone recordings, branch scripts and social updates should distinguish confirmed facts from estimates; say which services work; provide safe alternatives; and give a time for the next update even when there is no restoration estimate. Teams should also prevent outdated notices from remaining after a partial recovery changes the member experience.
Reconcile before declaring recovery complete
Restored access does not prove that every transaction, balance, authorization, deposit, payment file and downstream posting is complete. Operations teams need a controlled reconciliation window with expected totals, exception thresholds, ownership and a documented decision to return each service to normal processing.
The validation should cover transactions submitted just before the failure, activity attempted during the outage, queued files, duplicate risk, card authorizations, ATM withdrawals, deposits, scheduled payments and interfaces that may have resumed on different clocks. Evidence should be retained for internal audit, insurer and examiner review.
After the immediate incident, vendor-management leaders should compare actual performance with contracts, recovery commitments and prior findings. The vendor exit playbook provides a structure for evidence, transition dependencies and decision triggers. Even if the credit union stays with the provider, an exit-ready inventory clarifies which data, interfaces, people and timelines would be required to move.
The broader lesson is not that hosted cores are inherently unsafe. It is that concentration turns one physical incident into many member-service incidents at once. Credit unions need proof that redundancy is independent, restoration order is workable and recovery is complete—not simply a vendor promise that a backup exists.
Build resilience from evidence. Subscribe to the CreditUnionAI Weekly Briefing for practical AI, technology and operating-risk coverage.
Get the Weekly Briefing