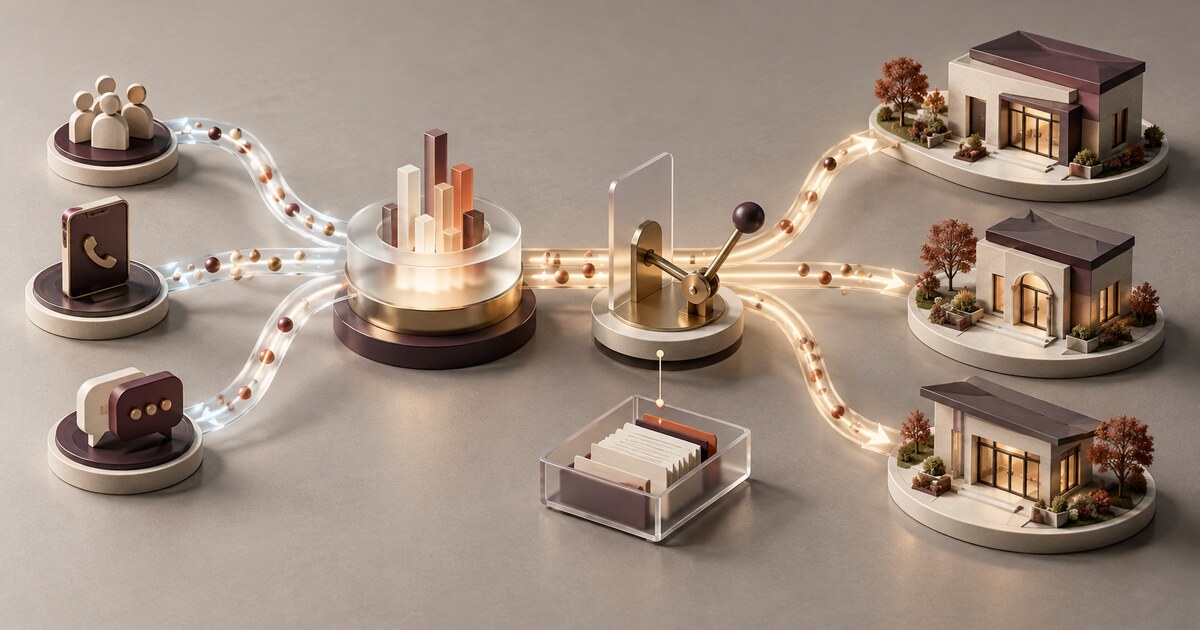
Branch planning is a natural forecasting problem. Credit unions already hold transaction volumes, appointment histories, teller activity, contact-center demand, digital adoption, local membership patterns and calendar effects. AI can combine those signals into a more timely view of when, where and why members seek service.
The risk is treating one forecast as an operating instruction. A model trained on recent traffic can mistake constrained access for low demand, shift work without measuring service quality, or hide the effect of a closure on members who cannot complete the same task digitally. A staffing recommendation can also become an employment decision without the controls expected for consequential workforce actions.
The NCUA’s AI resources emphasize governance, data quality, risk management, security and third-party oversight. The NIST AI Risk Management Framework adds a useful operating pattern: govern the use, map its context, measure performance and manage the response. Applied to retail delivery, that means leaders should approve the service objective and access boundaries before the model produces a forecast.
1. Start with a service map, not a foot-traffic target
List the member tasks delivered through each branch, shared branch, ATM, call center, video channel, appointment flow and digital experience. Distinguish a routine deposit from a task that requires identity proofing, cash handling, document review, translation, accessibility accommodation or trusted human support. Counting visits without classifying the work encourages a model to optimize transactions rather than service completion.
Define the planning objective in member terms: completed tasks within an approved wait, reliable access to cash, coverage for complex service, appointment availability or service continuity during a disruption. Record the cost and workforce measures separately. Leaders can then see when an efficiency recommendation conflicts with an access standard.
Evidence: channel-and-task inventory, task owner, service standard, access dependency, eligible alternatives and excluded high-consequence decisions.
2. Build auditable demand units and reconcile the inputs
A useful forecast needs more than door counts. Create demand units that reflect work: transactions, completed appointments, queue time, handling time, repeat visits, abandoned contacts, cash needs, escalations and unresolved digital journeys. Keep raw volumes alongside adjusted measures so a change in classification cannot silently rewrite the baseline.
Reconcile every source to an approved system of record. Check timestamps, branch identifiers, time zones, channel transfers, closures, weather events, marketing campaigns and system outages. A mobile outage can raise branch traffic; a temporary staffing shortage can suppress completed service. Both are operational events, not evidence of durable preference.
Use the NCUA’s quarterly credit-union data for external context, not as a substitute for local task-level evidence. The planning record should make clear which observations came from the institution, which came from a vendor and which are external benchmarks.
Evidence: data dictionary, reconciliation result, missing-data report, event annotations, source lineage and approved baseline period.
3. Separate the forecast from authority to change hours or staffing
The model may recommend a schedule, staffing mix or pilot. It should not publish branch hours, close a service lane, change employee assignments or initiate a network action. Put explicit decision rights in policy: who can approve a short-term schedule, who owns employment review, when compliance or accessibility review is required and which changes reach senior management or the board.
Each recommendation should show a range rather than a single precise number. Include expected demand, uncertainty, the most influential inputs, comparison with the approved baseline and the consequence if the forecast is wrong. Require a named decision owner to accept, modify or reject it with a reason.
Evidence: forecast version, confidence range, assumptions, prohibited actions, approver, final decision, variance from the recommendation and rationale.
4. Test access before treating low use as low need
Observed use is constrained by current hours, transportation, language support, physical accessibility, digital access and member awareness. A branch with low traffic may still be the only practical route for a protected or high-value service. Before reducing access, test travel time, appointment availability, accessible alternatives, cash availability, language coverage, shared-branch capacity and the failure mode when digital service is unavailable.
Do not use sensitive characteristics to reduce service. Where lawful and appropriate, aggregate outcome analysis can help leaders detect whether a proposed change places a disproportionate burden on a community or member group. The point is to challenge the plan, not to infer individual needs or target people.
Evidence: access impact assessment, alternative-channel test, outage scenario, accommodation review, community challenge and remediation decision.
5. Keep staffing recommendations out of consequential employment decisions
Demand forecasting can estimate coverage needs by role and time block. It should not become an opaque score for pay, promotion, discipline, performance or termination. Keep individual productivity metrics out of the branch-demand model unless a separate, approved workforce use case establishes necessity, validity, notice, review and appeal.
Measure workload after implementation. Watch overtime, schedule volatility, break coverage, queue pressure, error rates, escalations, training time and employee feedback. A plan that meets average wait time by creating unstable schedules or removing experienced coverage is not a successful operating result.
Evidence: approved staffing variables, excluded employee attributes, schedule-change limits, workforce review, employee feedback channel and workload scorecard.
6. Backtest across events, channels and underserved periods
Evaluate forecast error by branch, task, daypart, channel and event type. Include calm periods, benefit-payment dates, holidays, school calendars, severe weather, local events, digital outages and sudden cash demand. Compare the AI forecast with a simple seasonal baseline and the judgment of local operators.
Set investigation thresholds before launch. A forecast that is accurate on average can still fail during the opening hour, on Saturdays or at the one location supporting a specialized service. Review directional bias as well as magnitude: persistent underforecasting deserves a different response from random misses around zero.
Evidence: test periods, challenger forecast, error by service segment, peak-period result, bias review, root-cause analysis and approval to proceed.
7. Pilot reversibly and preserve the manual path
Begin with a bounded recommendation pilot. Hold branch locations and permanent staffing decisions constant while managers compare forecasts with actual demand. For later schedule tests, set a short duration, member notice, service-level thresholds, worker safeguards and an automatic rollback trigger.
Test the no-model path. Managers should be able to assemble the current demand view, apply approved minimum coverage, escalate an exception and publish an authorized schedule if the data pipeline or vendor is unavailable. Retain the inputs and decision record so a post-pilot review can distinguish model quality from execution failure.
Evidence: pilot charter, fixed boundaries, daily monitoring, stop conditions, manual worksheet, fallback exercise, member and employee feedback, and post-pilot decision.
A minimum weekly evidence packet
Operations, retail-delivery and workforce leaders should be able to review one compact packet containing:
- demand by task, channel, location and daypart, with reconciliation exceptions;
- forecast ranges, baseline comparison and the largest errors;
- wait time, abandonment, repeat contacts and service completion;
- access constraints, outages and alternative-channel capacity;
- staffing recommendations, authorized changes and overrides;
- workload, schedule stability, quality and employee feedback; and
- model, data, rule and service-map changes since the prior review.
If the packet cannot explain whether demand moved, access changed or the model changed, it cannot support a durable network decision.
Run five pre-launch tests
- Task test: trace ten common and five complex member tasks across every available service channel.
- Constraint test: replay a closure, digital outage, cash surge and accessibility accommodation request.
- Forecast test: compare the model with a seasonal baseline across normal, peak and disrupted periods.
- Authority test: submit a recommendation that would breach an approved service or staffing boundary and confirm it stops.
- Fallback test: lose the vendor or data feed, build the manual coverage plan and preserve the approval record.
AI can help a credit union see service demand earlier and allocate attention more deliberately. It should not collapse the distinction between observed traffic, member need and management authority. Build the service map first, measure constrained access, keep employment decisions separate and require every network change to remain explainable and reversible.
Plan retail delivery around tested member needs. Subscribe to the CreditUnionAI Weekly Briefing for practical implementation and governance coverage.
Get the Weekly Briefing